Journey
Naming objects in live video.
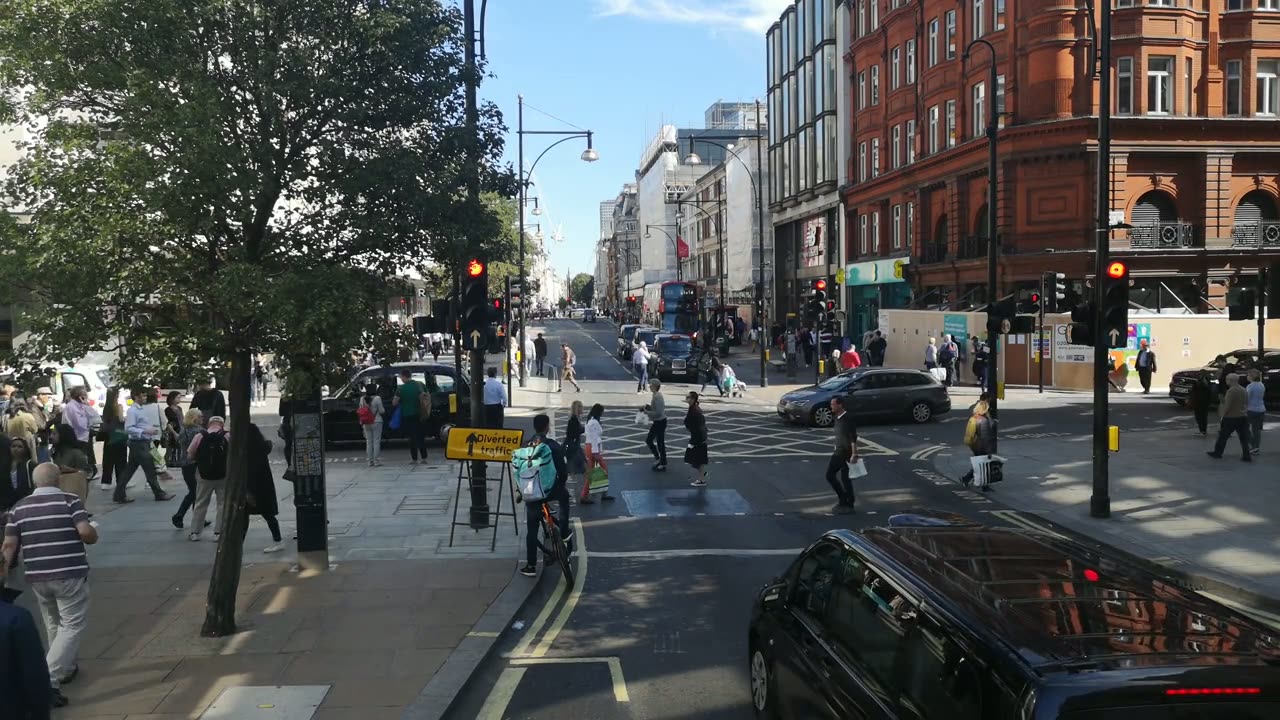
Raw street footage goes in. The engine learns the scene from the stream itself, groups movement into objects, gives each an identifier and follows it. There is no pretrained detector and no labelled training set.
What was measured
- The clip, and speed
- 2,580 frames of city footage at 320 by 240 pixels, at about 50 frames a second on one laptop core, learning as it went.
- Structure
- 55 states learned online, and 68,638 tracking events over the clip.
What was not measured
Accuracy against labels a person would give needs a labelled test set; until one has been run, no accuracy is claimed. A third of the tracks last a single frame, the next thing to improve.